Principles of the Transliteration (Add-On Version 3.4+)
Aramaic and Arabic are close relatives of Hebrew, and transliteration into the Hebrew writing system makes many words recognizable to a Hebrew speaker. The transliteration model is designed to make Arabic words easily recognizable to a Hebrew reader; pronunciation follows Literary Arabic.
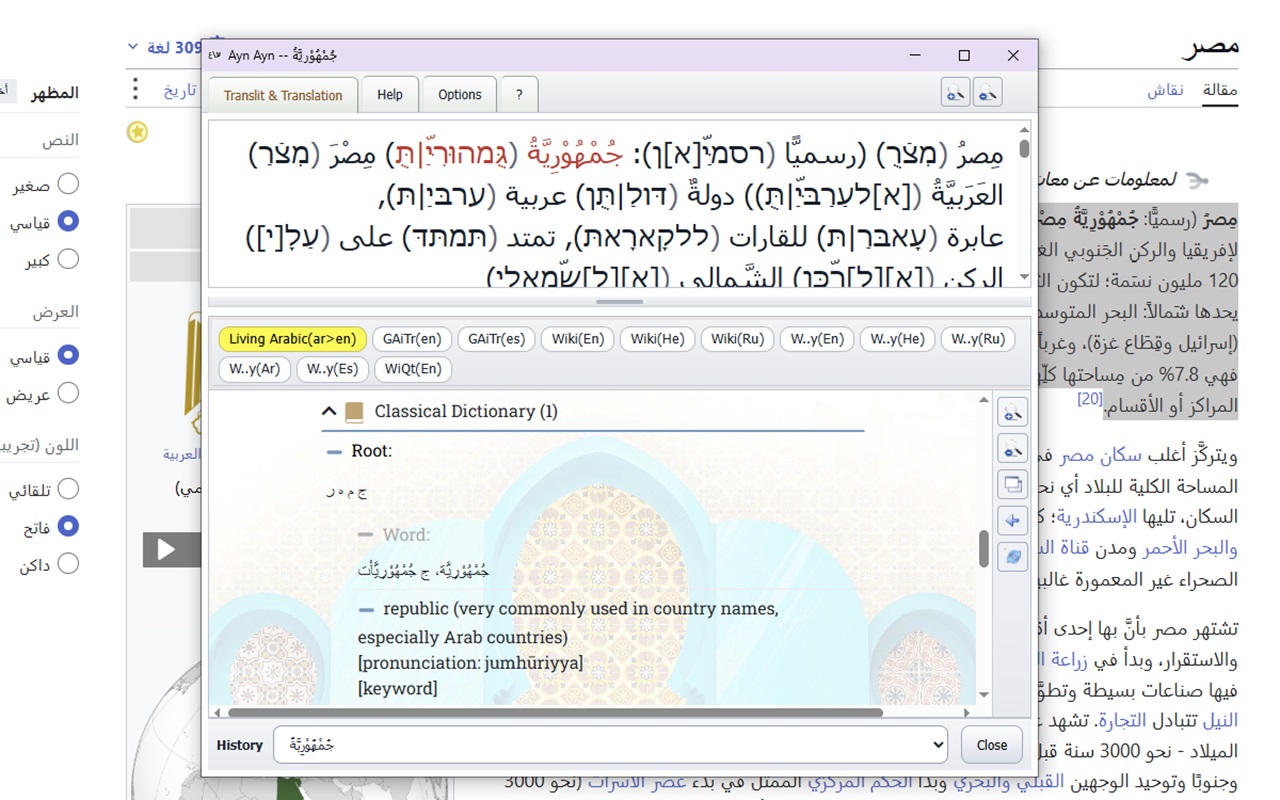
For Arabic words, the converter reads letters together with their vowel marks and uses the word form and surrounding text where the spelling is ambiguous. It recognizes the definite article with attached conjunctions or prepositions, but also distinguishes a similar beginning that belongs to the word itself. A silent article lam before a sun letter may appear in square brackets, as in (א[ל]שַّמס) الشَّمْس. When the article is clear, the converter can restore an unwritten shadda on the sun letter.
In Hebrew, the letters בגדכפת have, or historically had, two variants of pronunciation: plosive and fricative. Dagesh Qal denotes a plosive variant. The lesser-known overline called rafe may denote a fricative one. The converter uses both signs. It also uses geresh to mark a letter whose sound differs from its Hebrew pronunciation when both variants are plosive or both are fricative. Where possible, the converter does not use modern Hebrew geresh-based Arabic transliteration. In modern Israeli Hebrew, only ב, כ and פ still have two pronunciations. In Liturgical Mizrahi Hebrew, all בכפת letters have two pronunciations; ג and ד retain two pronunciations in Yemeni Hebrew. The converter uses Liturgical Mizrahi and Yemeni pronunciations of בגדכפת to reflect specific Arabic sounds in transliterated text.
In Arabic, פ/ف always represents F, ב/ب always represents B, and כ/ك always represents K. However, د ط ح ص ت, the equivalents of דטחצת, each belong to a pair of sounds, like Hebrew בגדכפת. The variant whose pronunciation differs from the basic Hebrew or Aramaic pronunciation—ordinarily a fricative—is marked with an additional dot that mostly acts like rafe. Although ح has the same sound as Mizrahi Hebrew ח, while خ has the same sound as כֿ, the converter maps خ to ח׳. Earlier versions used the phonetically consistent כֿ, but خ is linked etymologically with ח, not כֿ. It is thought that two Proto-Semitic sounds that remain distinct in Arabic merged into one Hebrew sound and letter. Conversely, one Arabic or Proto-Semitic sound represented by ك is thought to correspond to two distinct Hebrew sounds.
With dagesh and without rafe, דכת in transliterated text denote the same sounds as in modern Israeli Hebrew; ט represents the emphatic /tˤ/ of Arabic and some traditional Mizrahi Hebrew pronunciations. By default, Arabic plosive דּ and תּ retain dagesh. The Omit dagesh from ungeminated ד and ת option removes this plosive mark, including from Ta Marbuta rendered as ת; rafe continues to mark דֿ and תֿ. Dagesh is retained for written or restored Shadda, including when the geminated consonant is duplicated. Syriac Qushshaya always maps to Hebrew dagesh regardless of this option. In modern Israeli Hebrew, צ is pronounced as an affricate /ts/, which differs from both Arabic ṣād /sˤ/, a voiceless emphatic fricative, and ḍād /dˤ/, a voiced emphatic plosive. In the Tiberian reading tradition and Yemenite Hebrew, however, צ has an emphatic fricative pronunciation /sˤ/, similar to Arabic ṣād. To distinguish the two Arabic sounds explicitly, the converter uses צֿ with rafe for ص (ṣād), and צׄ with a dot above for ض (ḍād). The dot follows traditional Judeo-Arabic notation and makes the letter easier to read than the previously used dagesh. Within this transliteration system, the two signs distinguish the fricative and plosive sounds. The latter is pronounced similarly to a voiced alveolar plosive /d/, but with additional pharyngealization. For example, مصر (Egypt) is transliterated as מצֿר, while أرض (earth) is transliterated by default as ארץׄ, preserving recognizable Hebrew spelling. With rafe and without dagesh, the דטת letters denote the following sounds, as described in the IPA guide to Arabic:
| דֿ/ذ | the “th” sound in the English word “this” |
| טֿ/ظ | the “th” sound in the English word “thus” |
| תֿ/ث | the “th” sound in the English word “thin” |
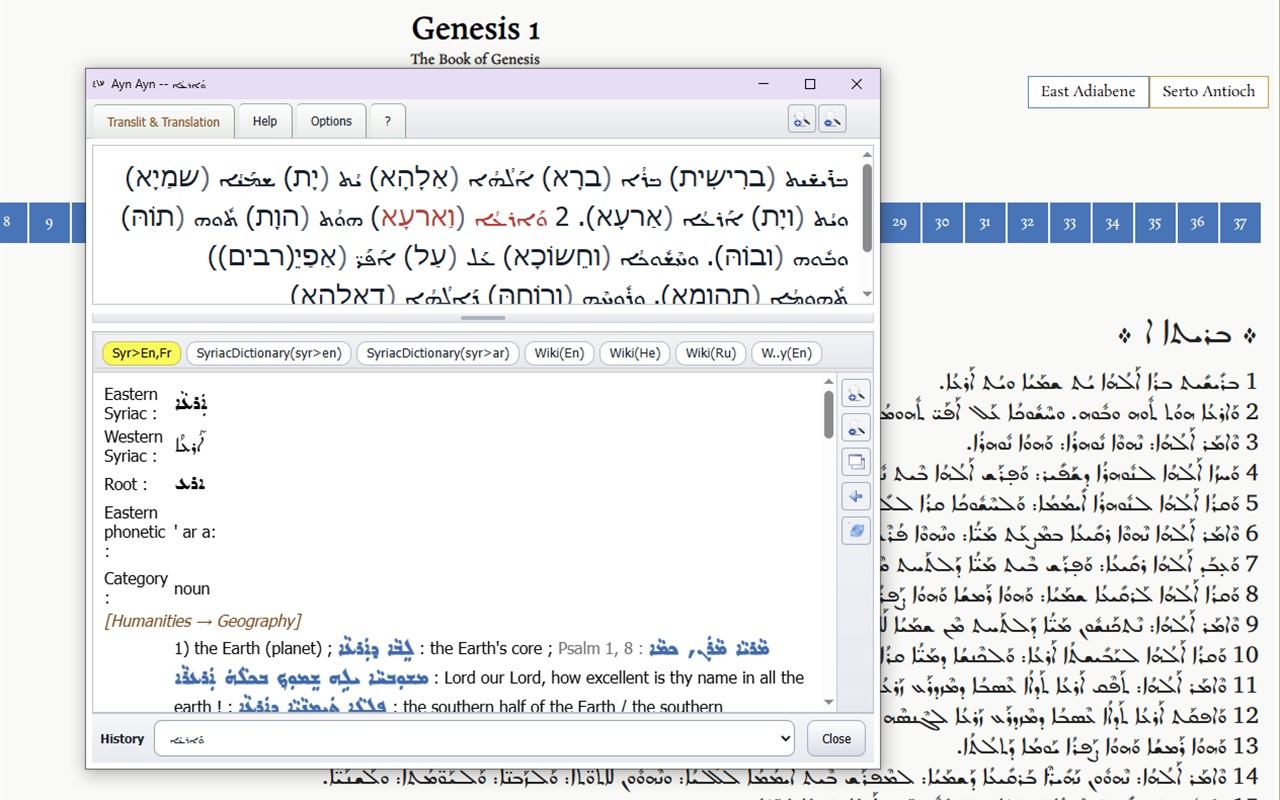
The letter غ GHAYN denotes an R-like sound, the voiced uvular fricative. Many Ashkenazi Jews pronounce ר this way. It would be phonetically consistent to transliterate غ as רֿ, but the converter maps it to ע׳ because غ is linked etymologically with ע, not ר. In converted Syriac text, softened gamal is rendered as גֿ; for example, ܒܓ݂ܕܕ → בגֿדד. A special dot “רוככא” marks a “soft” letter in the original text.
The letters ر/ר represent the same sound. In Arabic, it is a trill close to the Amharic or Russian R. This sound is very difficult for most Ashkenazi Jews to pronounce. During the Holocaust, local Nazi collaborators in Eastern Europe used the Russian word “KUKURUZA”/“кукуруза” as a shibboleth to identify Jews for extermination.
The letter and diacritic sign ء HAMZA , whether written independently or on a carrier, denotes a glottal stop /ʔ/, while ordinary Arabic alif without HAMZA often represents a long /aː/ vowel. The converter represents HAMZA by Hebrew alef א, which historically denotes the same consonant. In pointed Hebrew, an alef carrying its own vowel point normally represents a consonant rather than a vowel letter. The converter follows this principle: an alef bearing an ordinary vowel point, shva, or a hataf is treated as consonantal. A word-initial alef is also consonantal even without pointing. A shva belonging to the immediately preceding consonant is retained where appropriate, allowing HAMZA's alef to carry its following vowel directly.
Alif can also preserve an older orthographic notation of a glottal stop. In traditional spellings such as مِائَة (one hundred), this retained alif occurs alongside the modern seated HAMZA denoting the same glottal stop. The duplication is orthographic, not phonetic: the alif itself is now ignored. The Add-On omits it without square brackets and handles HAMZA normally; for example, مِائَة → מִ[י]אֲ|תּ with hataf-patah enabled. This handling applies to a bare alif, with neither HAMZA nor its own vowel except optional sukun, after kasra before HAMZA on yeh, or after damma before HAMZA on waw. Missing vowels in recognized hundred-word forms are recovered only where unambiguous, with one practical exception: unpointed مائتان and مائتين are preferentially read as the numeral 200. Explicit conflicting vowel marks take precedence; other ambiguous forms such as مائتي are not covered by this preference, and competing morphological analyses are retained. The same omission is applied before Ancient Hijazi reading reconstruction: the retained alif is not treated as a long /aː/ vowel, and the following HAMZA is then processed according to that mode's reconstruction rules. For the historical orthography, see Al-Jallad (2021), §3.2.
The Add-On represents HAMZA together with its following short vowel using either an ordinary Hebrew vowel point or a hataf, according to the selected options. This applies both to vowels explicitly written in the Arabic text and to unwritten vowels that can be reliably inferred from HAMZA's position, carrier, and context. The choice of notation depends on the vowel being represented, rather than merely on the Arabic letter carrying HAMZA. Hebrew hatafs traditionally represent reduced vowels and occur primarily under guttural consonants. In this transliteration, however, they are used as an alternative notation for HAMZA followed by an ordinary short Arabic vowel, without implying any additional vowel reduction. For short /a/ (Arabic fatha), the available notations are hataf-patah אֲ and ordinary patah אַ. For short /i/ (Arabic kasra), the available notations are ordinary hiriq אִ, synthetic hataf-hiriq אְִ, and hataf-segol אֱ. Synthetic hataf-hiriq combines shva and hiriq on the same alef. Although this is not a traditional Hebrew hataf, it expresses the intended /i/ vowel while retaining the visual shva component. Hataf-segol is another optional approximation, although the corresponding Hebrew vowel differs from Arabic /i/. For example, إِ → אְִ when synthetic hataf-hiriq is selected. For short /u/ (Arabic damma), ordinary qubuts אֻ provides the closer phonetic correspondence. Hataf-qamatz אֳ can be selected as an alternative. In Hebrew, hataf-qamatz represents a reduced /o/-like vowel, historically [ɔ̆], rather than /u/. Although both are rounded back vowels, they are not identical. Traditional Hebrew has no hataf-qubuts sign.
When a corresponding hataf option is disabled, the Add-On uses the ordinary Hebrew vowel point directly beneath HAMZA's alef: patah for short /a/, hiriq for short /i/, and qubuts for short /u/. An alef carrying its own vowel point is already consonantal, so no additional alef with shva is inserted merely to carry an explicitly written vowel. If the preceding consonant has sukun, its corresponding Hebrew shva is retained on that consonant, and HAMZA takes its following short vowel directly, regardless of the hataf settings.
Hatafs can represent only short vowels. Long vowels following HAMZA are therefore written using the ordinary Hebrew notation for long vowels, regardless of the hataf settings: qamats for /aː/, hiriq male for /iː/, and shuruk for /uː/. The same consonantal alef carries qamats or hiriq and represents the glottal stop: medial /ʔiː/ is written אִי. Before shuruk, the vowel point belongs to waw rather than alef, so a medial consonantal alef retains its shva: אְוּ. At the beginning of a word, this shva is omitted because the initial alef is already consonantal.
When HAMZA's following vowel is not explicitly written, the converter attempts to recover it from HAMZA's position, carrier, and linguistic context. Although these provide useful clues, they do not always determine the vowel unambiguously. Where a short vowel can be reliably recovered, it is represented just like an explicitly written vowel, using the selected hataf or ordinary vowel point. When the vowel cannot be determined, a consonantal alef within or at the end of a word retains the Arabic HAMZA sign above it: אٔ. This distinguishes it from a vowel-lengthening alef without implying that no vowel follows. Shva is retained where sukun establishes the absence of a vowel, including at the end of a word. For example, سأل → סאٔל and شيء → שיאٔ. At the beginning of a word, neither this HAMZA sign nor a consonantal shva is added, since the initial alef is already unambiguously consonantal. For example, when the initial vowel cannot be determined, أغلب → אע׳לבּ. This omission does not affect shva when it forms part of synthetic hataf-hiriq אְִ. When the initial vowel is known, the corresponding ordinary vowel point or hataf is placed directly on the initial alef. No additional alef with shva is inserted before it. For example, إيمان → אִימָאן when ordinary hiriq is selected. Within a word, however, if an unwritten kasra is represented by ordinary hiriq, a separate alef may carry that vowel after אְ where necessary to preserve the explicit consonantal marker. The omission of redundant initial shva does not remove a hataf or the shva belonging to a preceding consonant.
Meteg מֶתֶג, also called gaʿya גַּעְיָה, is a traditional Hebrew reading sign: a small vertical stroke below the letter, usually to the left of its vowel point, as in אָֽ. In pointed Tanakh Hebrew, it can mark secondary stress and indicate that a vowel should receive a fuller or lengthened pronunciation. Its precise function depends on the reading tradition and phonological context. See Gesenius, §16. AynAyn uses this association with sustained pronunciation to represent the vowel elongation indicated by Arabic Madda. This is a transliteration convention, not an assertion that Hebrew meteg and Arabic Madda have identical historical functions.
Alif Madda آ denotes /ʔaː/ and is written אָֽ: one consonantal alef with qamats and meteg. No additional alef with shva is inserted. A preceding consonant's shva is retained where appropriate; for example, قُرْآن → קֻרְאָֽן.
Standalone Qur'anic Madda marks ٓ and ۤ indicate vowel elongation. The converter represents this indication by meteg next to the corresponding Hebrew vowel, including hiriq male and shuruk, without adding another HAMZA. Meteg follows the vowel when its written Arabic carrier differs from the Hebrew vowel's carrier, and repeated marks for the same vowel produce one meteg. By default, a separately typed alif + Madda is treated as elongation; turning off Read standalone Madda as vowel elongation permits an ambiguous combination to be read as Alif Madda. Alif after written fatha remains a vowel-lengthening carrier.
For example, the modern Arabic spelling إِسْرَائِيل is transliterated as אְִסרָ[י]אִיל when synthetic hataf-hiriq is selected. The Qur'anic spelling إِسْرَٰٓءِيلَ is transliterated as אְִסרָֽאִילַ under the same setting. In both forms, the initial HAMZA with short /i/ is represented by synthetic hataf-hiriq, while the medial HAMZA before long /iː/ requires ordinary hiriq male on the same consonantal alef. Meteg preserves the written Madda's indication of elongation. Square-bracketed י or ו associated with HAMZA are annotations of its source spelling carrier.
The Add-On also provides an Ancient Hijazi reading reconstruction mode, based on research into the early Qur'anic consonantal text and its historical pronunciation. In this mode, HAMZA is generally omitted in positions where it is reconstructed as absent from Ancient Hijazi pronunciation, and the corresponding historical vowel sequences or long vowels are reconstructed instead. Written Madda's meteg is retained with the resulting vowel.
ى ʾalif maqṣūrah (ألف مقصورة) denotes a long /aː/ vowel at the end of a word in Literary Arabic. It looks like a dotless ـي. The converter marks the long vowel with kamatz and may show the silent source letter in square brackets, as in عَلَى → עַלָ[י]. Egyptians often omit the dots from final ي, making it look like alif maqsurah. The converter uses vowel marks, recognized word forms, and related forms in the same text to distinguish the two readings. When the evidence identifies an undotted final yeh, it renders Hebrew י; for example, فِى → פִֿי. Recovery is not applied when the reading remains ambiguous.
The shva in converted Arabic text should not be pronounced as an additional vowel. When it corresponds to sukun (سكون), it denotes the absence of a following vowel. An unknown vowel after noninitial HAMZA is instead indicated by the Arabic HAMZA sign above Hebrew alef, אٔ. Kamatz denotes long /aː/ in converted Arabic and Eastern Syriac texts, but /o/ in converted Western Syriac.
Qur'anic initials are read by letter names when their characteristic marks identify them; for example, الٓمٓ → אֲלִףֿ לָֽאם מִֽים. Unmarked الم is also read by letter names before ذلك when preceded by the full basmala or followed by the first-verse marker. Elsewhere, the unmarked form remains ambiguous.